Dashboards are where marketing data goes to die. We connect the sources, build the charts, and every Monday numbers are updated. But nobody owns the interpretation, and the client is still left asking the only question that matters: where should the next euro go?
At MeasureCamp Stockholm on November 7, I ran a session on how we’ve tackled this for a few client accounts: an AI analyst that does the weekly analysis, working under a human lead. It’s not a vendor pitch. The slides are right below, and the rest of this post walks through the actual workflow.
The slides
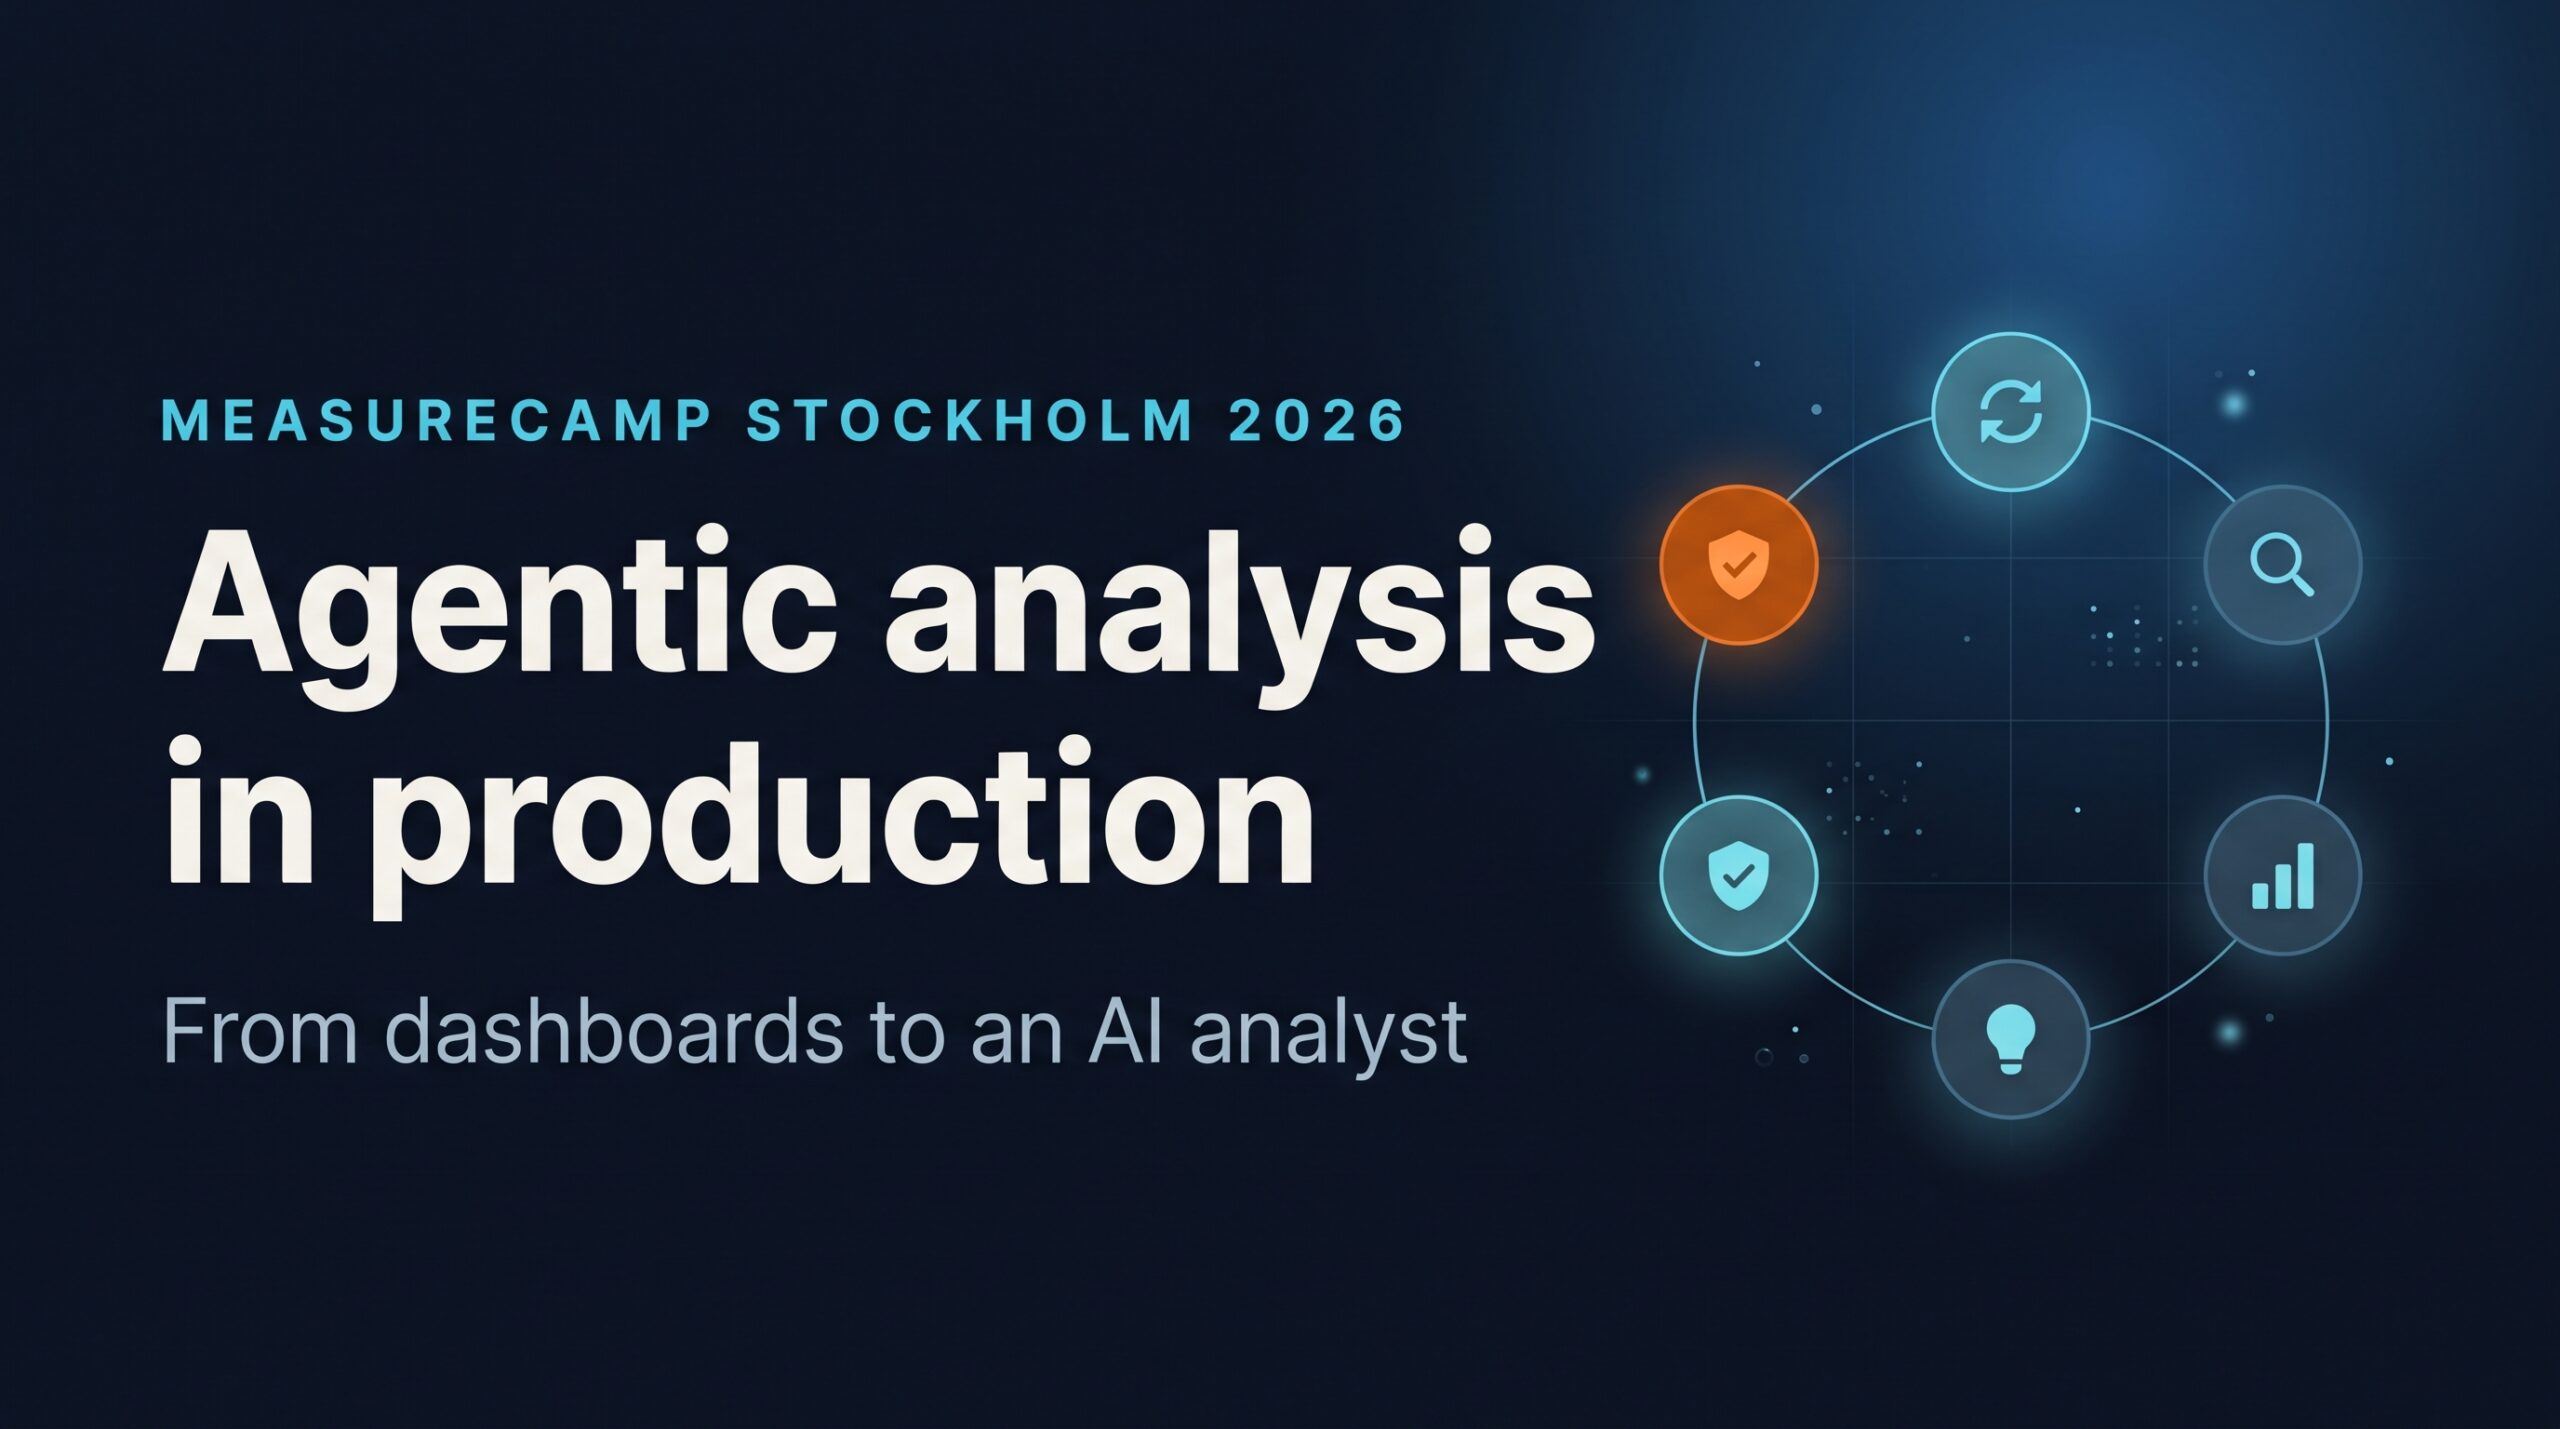
MeasureCamp Stockholm · 7 Nov 2026Agentic analysis in productionFrom weekly dashboards to an AI analyst that recommends, not just reportsView the slides →An AI analyst, not another dashboard
Think of the agent as a junior data scientist who never gets tired of Mondays. It pulls and joins the data every morning, runs tracking health checks, works out what changed and why, and drafts recommendations with a confidence level. The human analyst sets the rules and the business context, reviews and grades every recommendation, talks to the client and owns the decision.
The stack is deliberately boring: Coupler.io flows for the shop and ad platform data, MCP servers for GA4 and Google Ads, and the owner’s own sales and purchase Excel files from Google Drive. These feed a Claude project. The pipes are the easy part. What makes it work is the role definition, the data and business context, and the guardrails. And rule number one: every number in the output traces back to a query you can open.
One weekly loop, six steps
- Refresh: all sources refresh every morning at 07:00.
- Check: on Monday, tracking health is checked before any performance claim.
- Analyse: what changed, why, and what it cost.
- Recommend: an action with an owner, a confidence level and a way to verify it.
- Review: the human analyst grades it before the client sees it.
- Verify: next week’s run checks whether last week’s advice worked, and the agent learns from the corrections.
Check the data before you trust the data
This is the step most AI reporting demos skip. A fixed set of checks runs first: duplicate transactions, (not set) spikes, consent share, gaps between platform and GA4 numbers, and odd traffic. Fixed checks detect the problem; the model investigates and explains it in plain language. In practice it’s technical monitoring that runs every week.
In one recent week, the checks caught about 11,000 short direct desktop sessions from abroad with zero purchases, which would have made the conversion rate look terrible. They also found payment providers taking around 5% of revenue credit as referrers. Both went into the report as caveats, so the client didn’t react to a fake drop.
Join ad data with the business’s own numbers
This is where an agent beats a dashboard. For one e-commerce client, the agent combines ad data with margin, purchases, stock and new listings. Gross margin varied from 7% to 30% between brands, one brand made up more than half of online sales, and new listings of that brand had dropped 57% from their usual pace three weeks before Black Friday. So the top recommendation that week was about securing stock, not ad budgets. No ads-only report could have said that.
A recommendation is a testable hypothesis
Every recommendation has five parts: the finding, the action, the owner, the confidence with its reason, and the metric that verifies it. If one of the five is missing, it’s an observation, not a recommendation. For example: raise Google Shopping to about €20 a day for the season, because €66 of spend brought two orders at around €0.07 a click. Confidence is medium, since volumes are small and Google’s own ROAS runs high, and the result is verified against GA4 and total shop sales.
Every correction becomes a rule
If you take one thing from this post, take this. I grade every diagnosis as right, partly right or wrong. Every correction goes into a dated refinements log with the rule and the reason, and that log is loaded on every run, so the same mistake doesn’t happen twice. Real examples: count sessions only from session_start rows, merge rate plans by ID rather than name, exclude test and cancelled orders, treat platform ROAS as a ceiling rather than a fact. The grading is also how the agent earns autonomy, one task at a time.
Guardrails
- Numbers come from queries, never from the model’s memory or arithmetic in prose.
- Access is read-only by default. GTM changes are prepared in a workspace and never published by the agent.
- Client emails and Slack posts are drafts that wait for human review.
- Every claim carries a confidence level, with the reason and what would change it.
- Platform-reported conversions are always labelled as such.
- Only aggregated data is processed, and the AI vendor is named as a subprocessor in the data processing agreement.
What broke along the way
Dataset IDs changed on every refresh, so sources are now resolved by name at the start of each run. Local connectors needed my laptop to be on, so scheduled work is moving to cloud connectors. The owner’s Excel had gaps, and the gap itself became a recommendation. Small volumes swing a lot from week to week, so comparisons are made against last year and four-week averages. And the agent couldn’t prove that Meta works from attribution data alone, so it says confidence is low and we’ll run a holdout test in January.
Want to talk about how this could work for your marketing data?